ETL Validator
ETL Validator for Faster Pre-Deployment Checks
Catch mapping and schema issues earlier
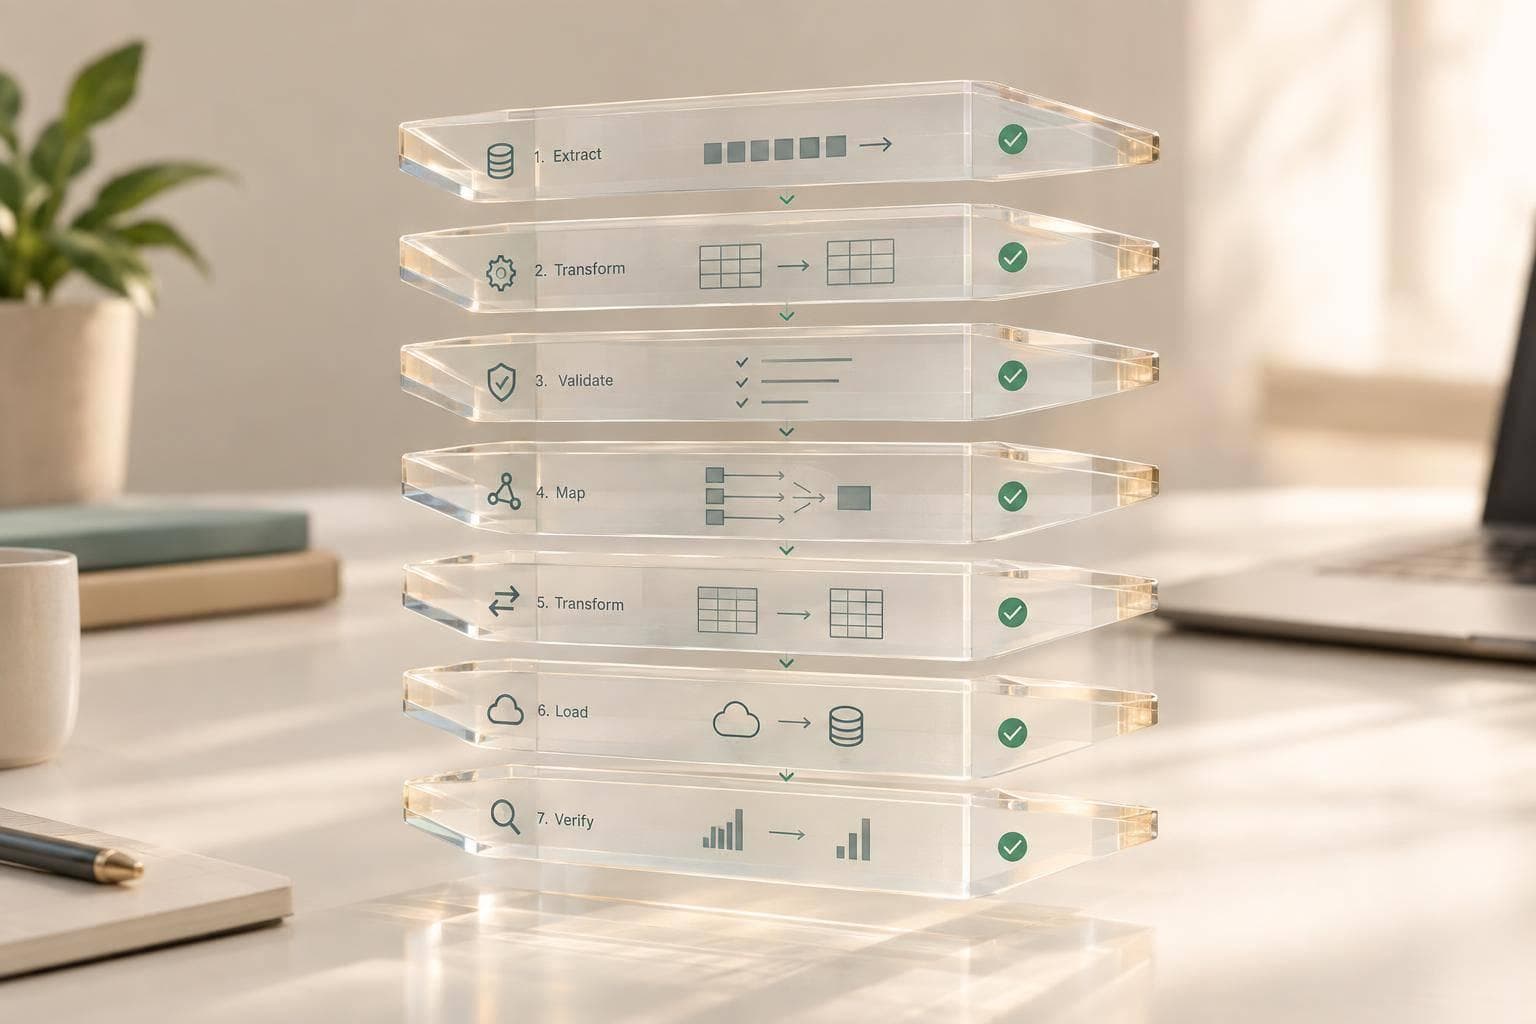
An ETL Validator gives data engineers and QA teams a faster way to review pipeline logic before formal testing starts. Instead of scanning spreadsheets and mapping documents by hand, teams can compare source and target schemas, confirm required field coverage, and spot risky transformation rules in one place. That makes it easier to identify missing fields, incompatible data types, nullability conflicts, and unclear defaults before they turn into production defects.
Review mappings, rules, and reconciliation together
This tool is especially useful when you're working across multiple tables, flat files, or evolving warehouse models. You can validate mapping definitions, inspect transformation logic for gaps, and check whether target fields are backed by a source value, a derived rule, or an explicit default. If sample records are available, the ETL Validator can also highlight row-count deltas, duplicate concerns, null handling problems, and format mismatches that deserve closer review.
Built for practical ETL QA workflows
Because ETL testing often starts with incomplete information, the tool separates hard errors from warnings and calls out items that need manual review. It supports a practical validation workflow built around schema checks, reconciliation, and data quality review without overstating what can be proven from limited inputs.
FAQs
What can this ETL Validator actually verify?
It can review schema consistency, target field coverage, transformation rule completeness, nullability mismatches, duplicate risks, and row-count reconciliation. If you provide sample records, it can also flag basic data quality concerns such as null handling, format mismatches, and count deltas. It does not claim to fully execute your ETL logic unless actual samples and usable rules are included.
Do I need sample data to use the tool?
No. You can still validate mappings, schema definitions, required defaults, and transformation coverage using metadata alone. Sample source and target records simply make the review stronger because they allow the tool to check practical issues like duplicates, missing values, simple format inconsistencies, and reconciliation differences.
How are the results presented to engineers and QA teams?
The output is split into clear sections such as schema issues, mapping gaps, transformation concerns, data quality checks, and reconciliation results. Hard errors are separated from warnings, and each finding points to the affected field, rule, or area of concern. You also get a concise next-steps section that helps teams decide what should be corrected before deployment or test execution.