Mlops
19 articles tagged with "Mlops"
Provisioned Concurrency vs On-Demand: Latency Tradeoffs
Measure P95/P99 before paying for provisioned concurrency — choose on‑demand or provisioned to balance tail latency, cost, and spikes.
Fraud Detection with Streaming Data: Use Cases
Use streaming events plus historical context to detect fraud across banking, e‑commerce, insurance, and telecom—making fast, accurate risk decisions.
Securing Event-Driven Architecture: Best Practices
Checklist to secure event-driven systems: map flows, enforce least privilege, validate schemas, protect identities, control retries, and audit.
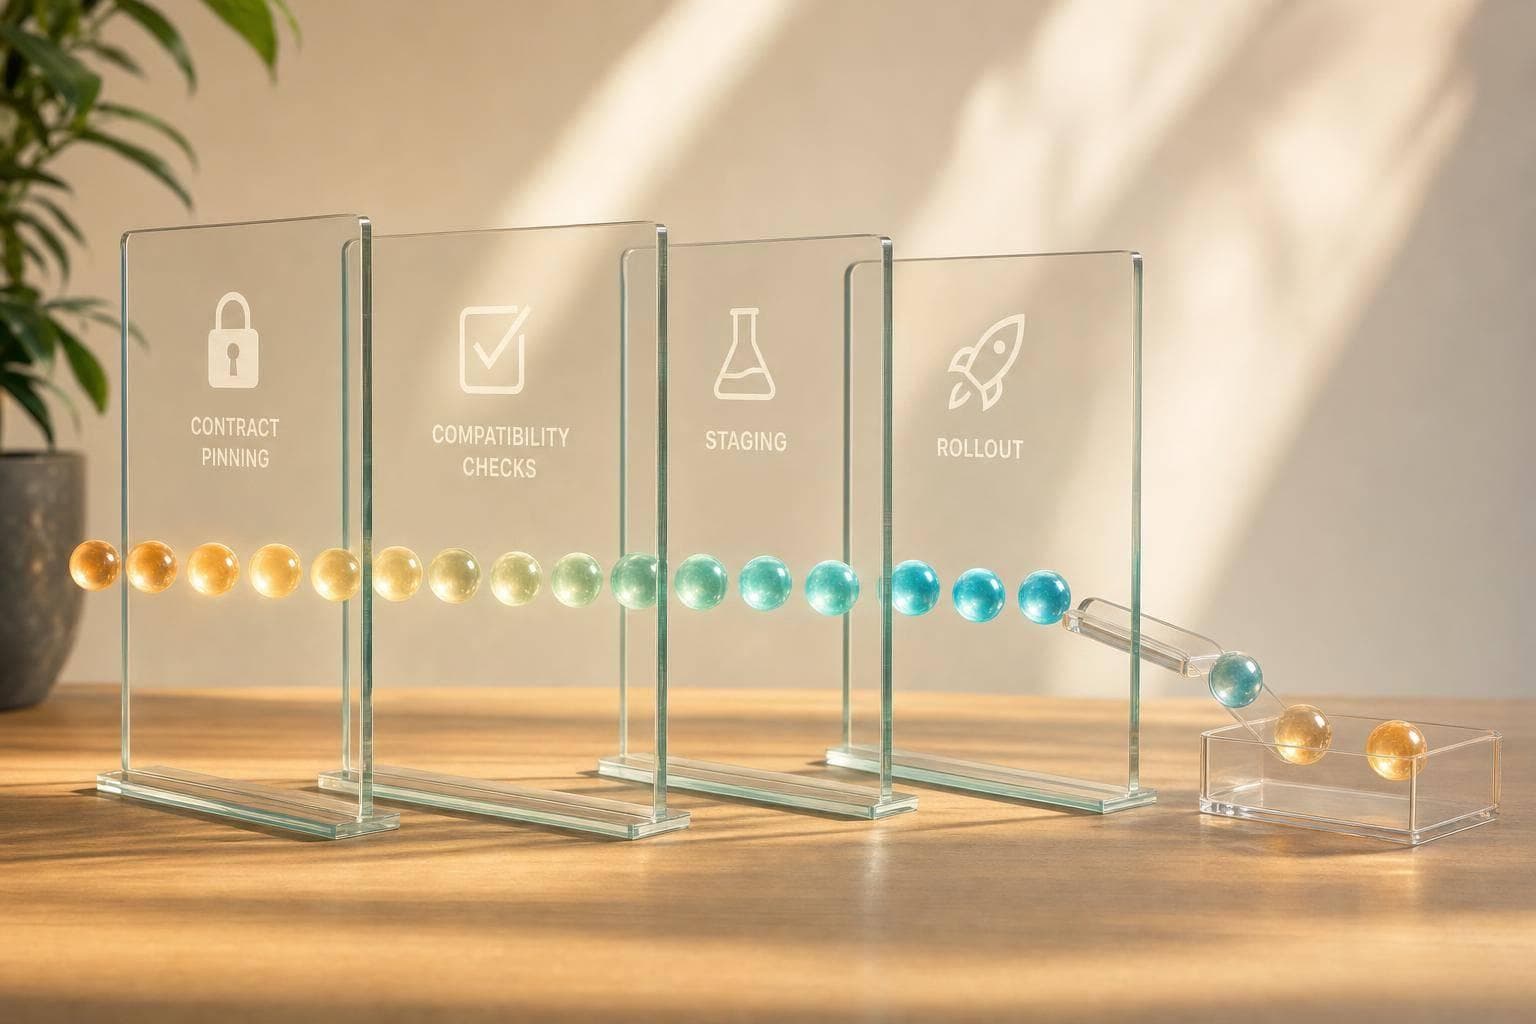
Handling Schema Drift in Event Streams
Prevent and contain schema drift in event streams: pin contracts, run compatibility and staging tests, use DLQs and staged rollouts.
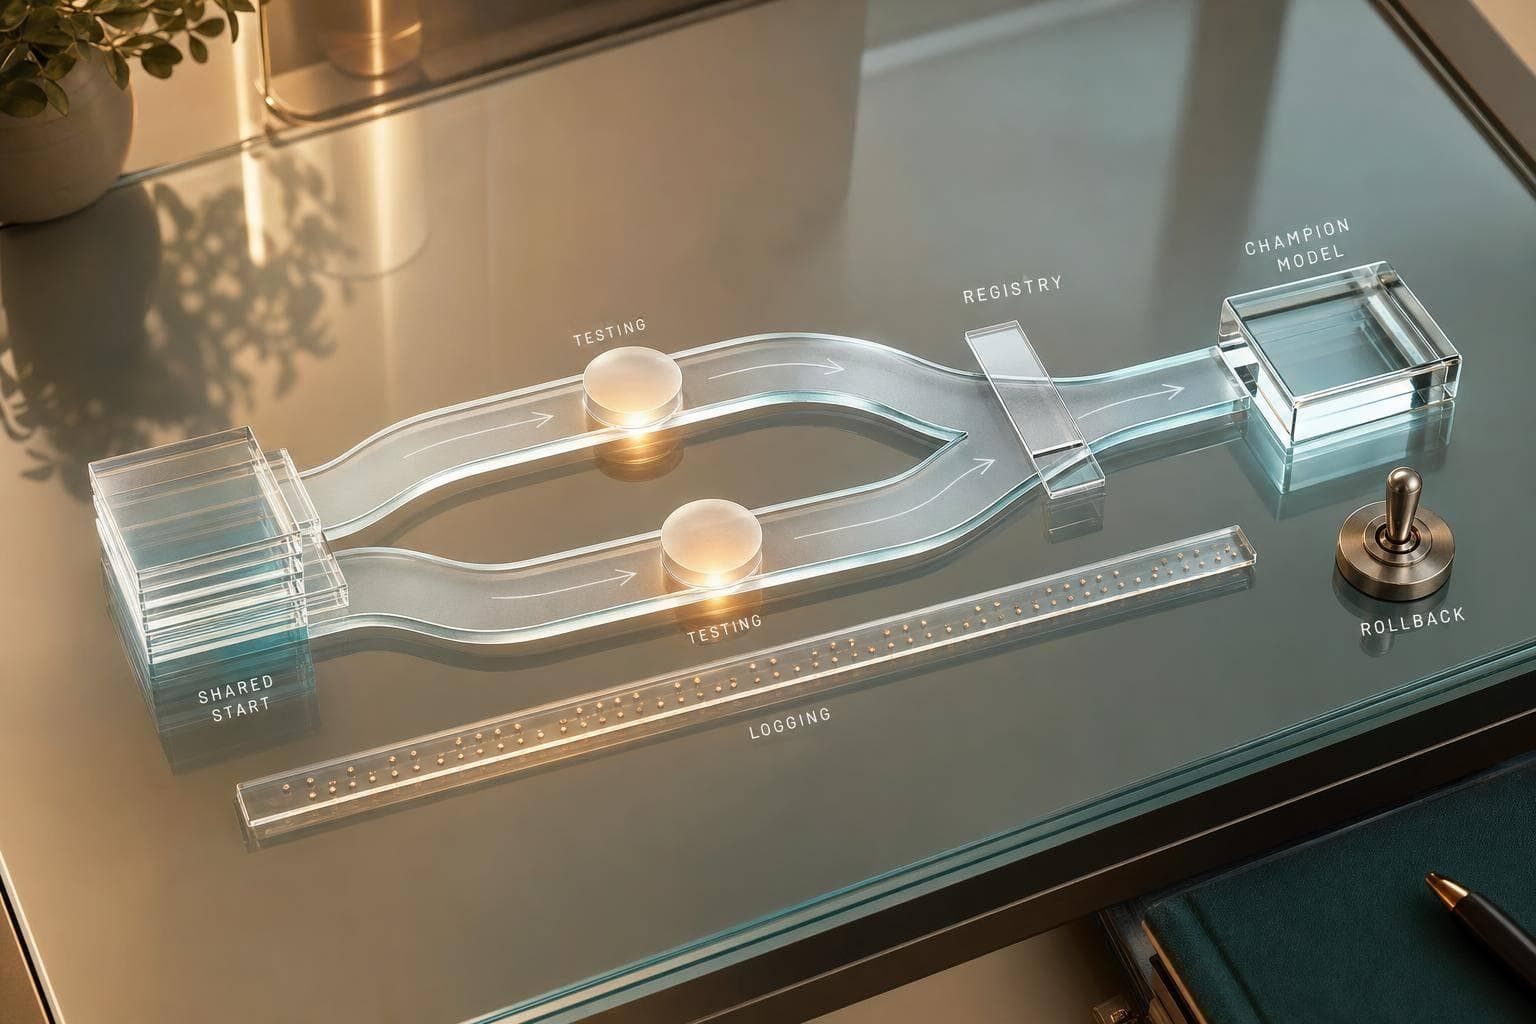
Champion-Challenger Guide for Lakehouse ML
Repeatable champion-challenger process for lakehouse ML: shared features, registry aliases, shadow/canary tests, logging, and rollback.
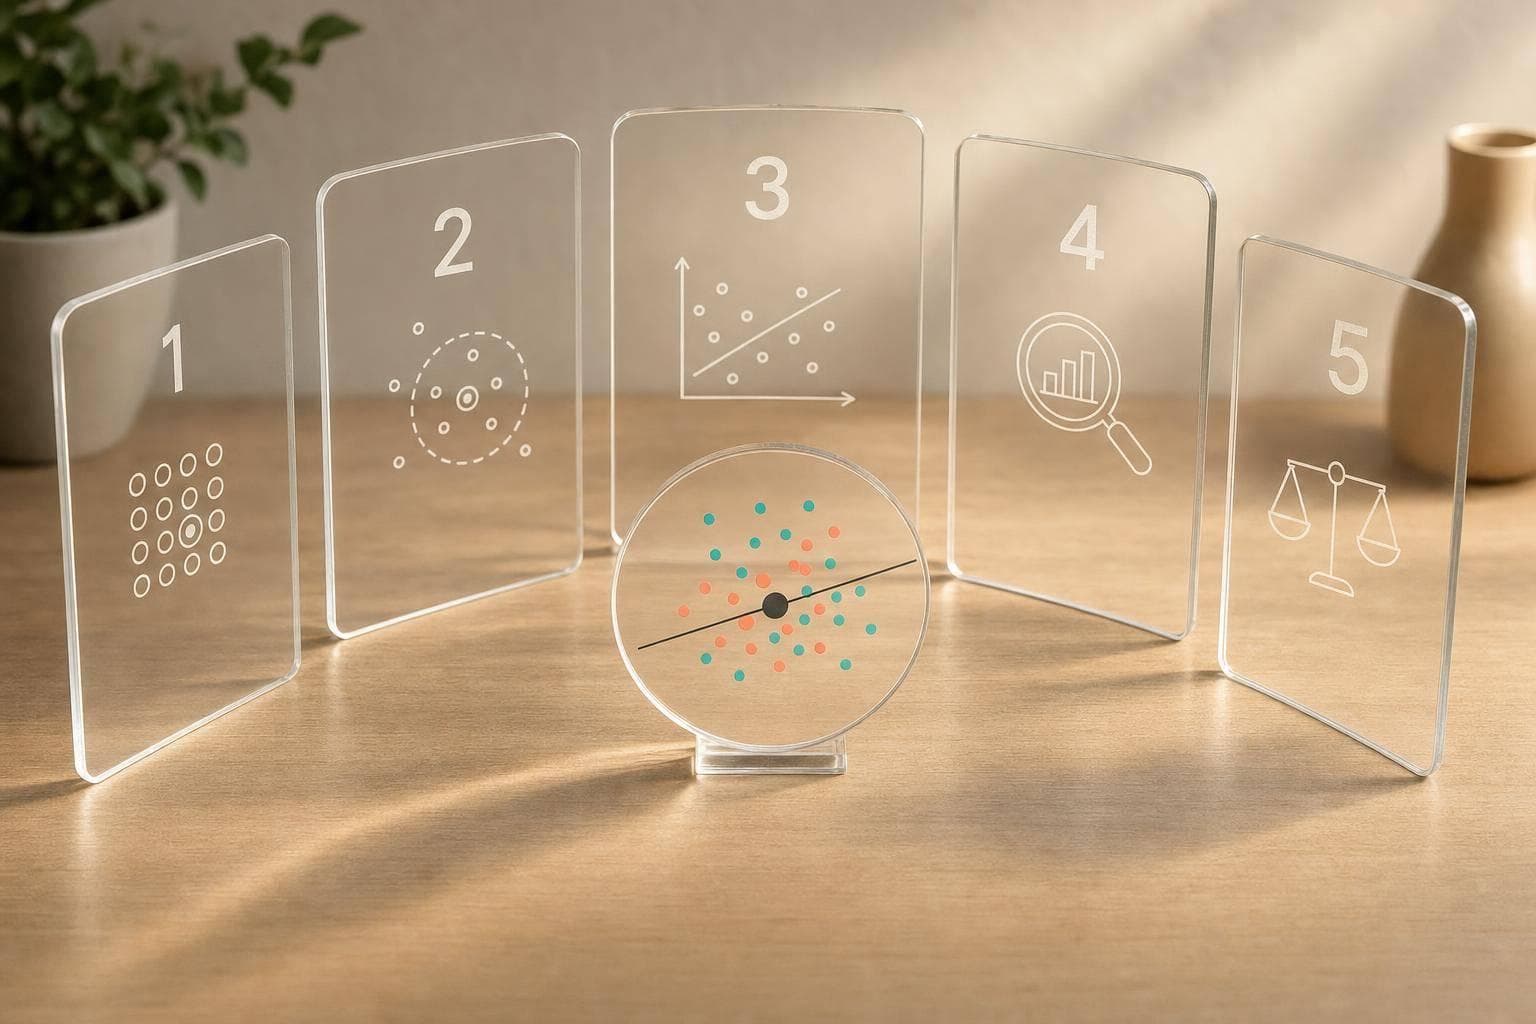
LIME for ML Models: 5-Step Guide
Use LIME to explain single-model predictions: build local samples, fit a weighted surrogate, and verify stability, fidelity, and scope.
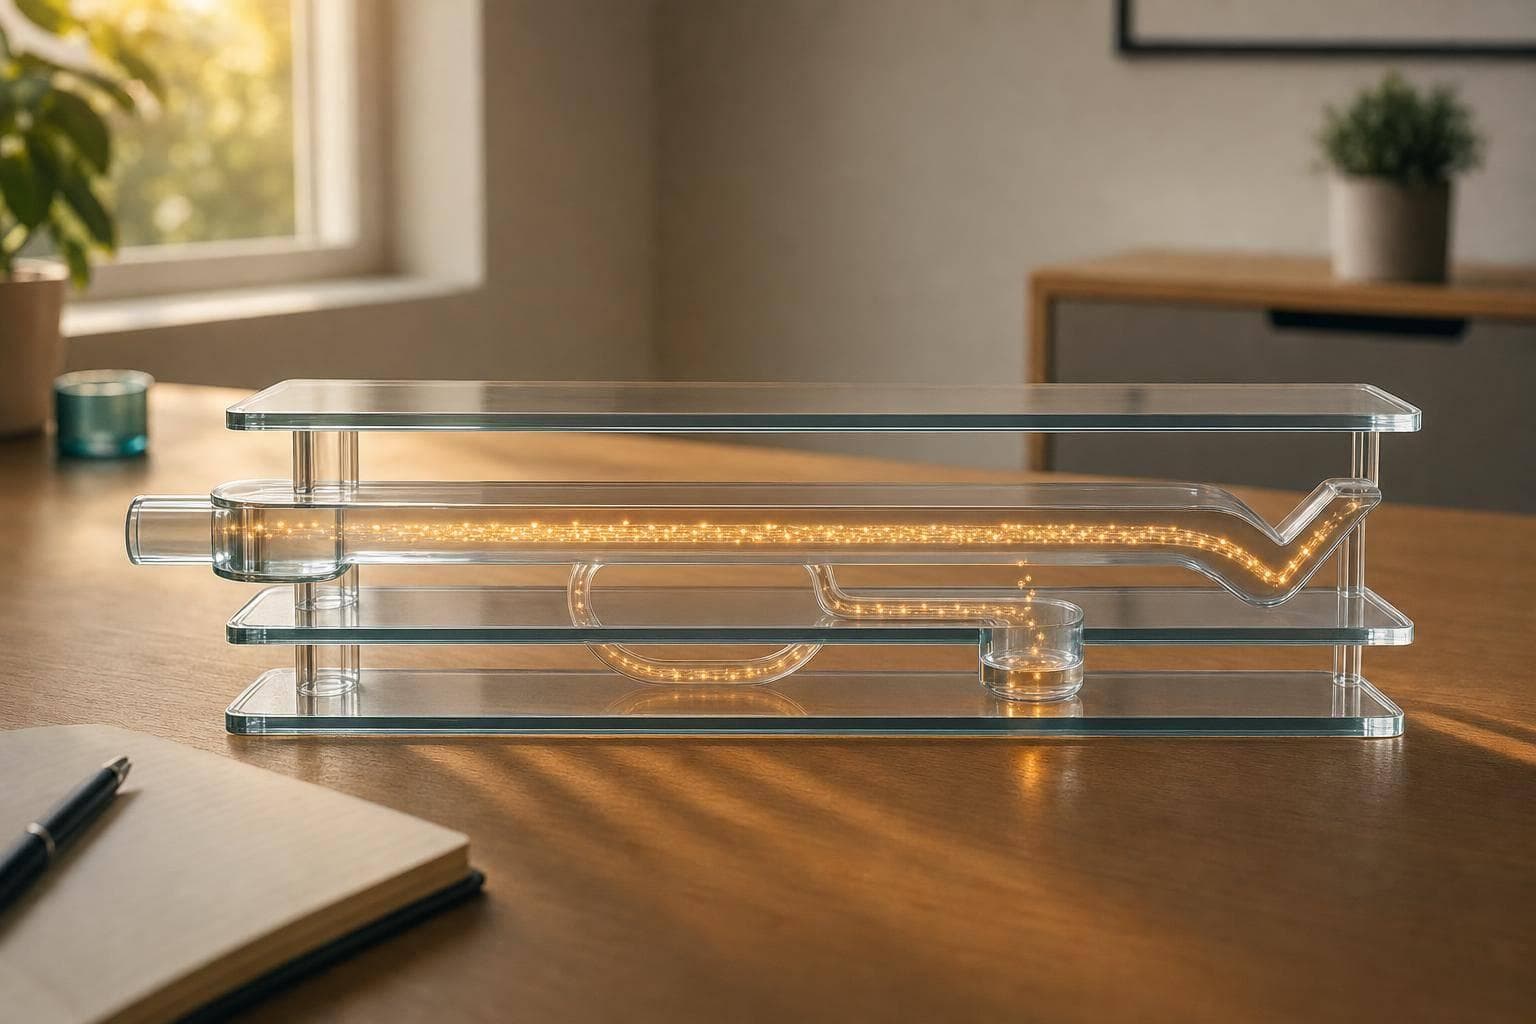
How to Build AI Streams with Kafka and Flink
Low-latency AI streams: use Kafka to ingest, Flink to build features and score, with replay, lateness handling, and exactly-once delivery.
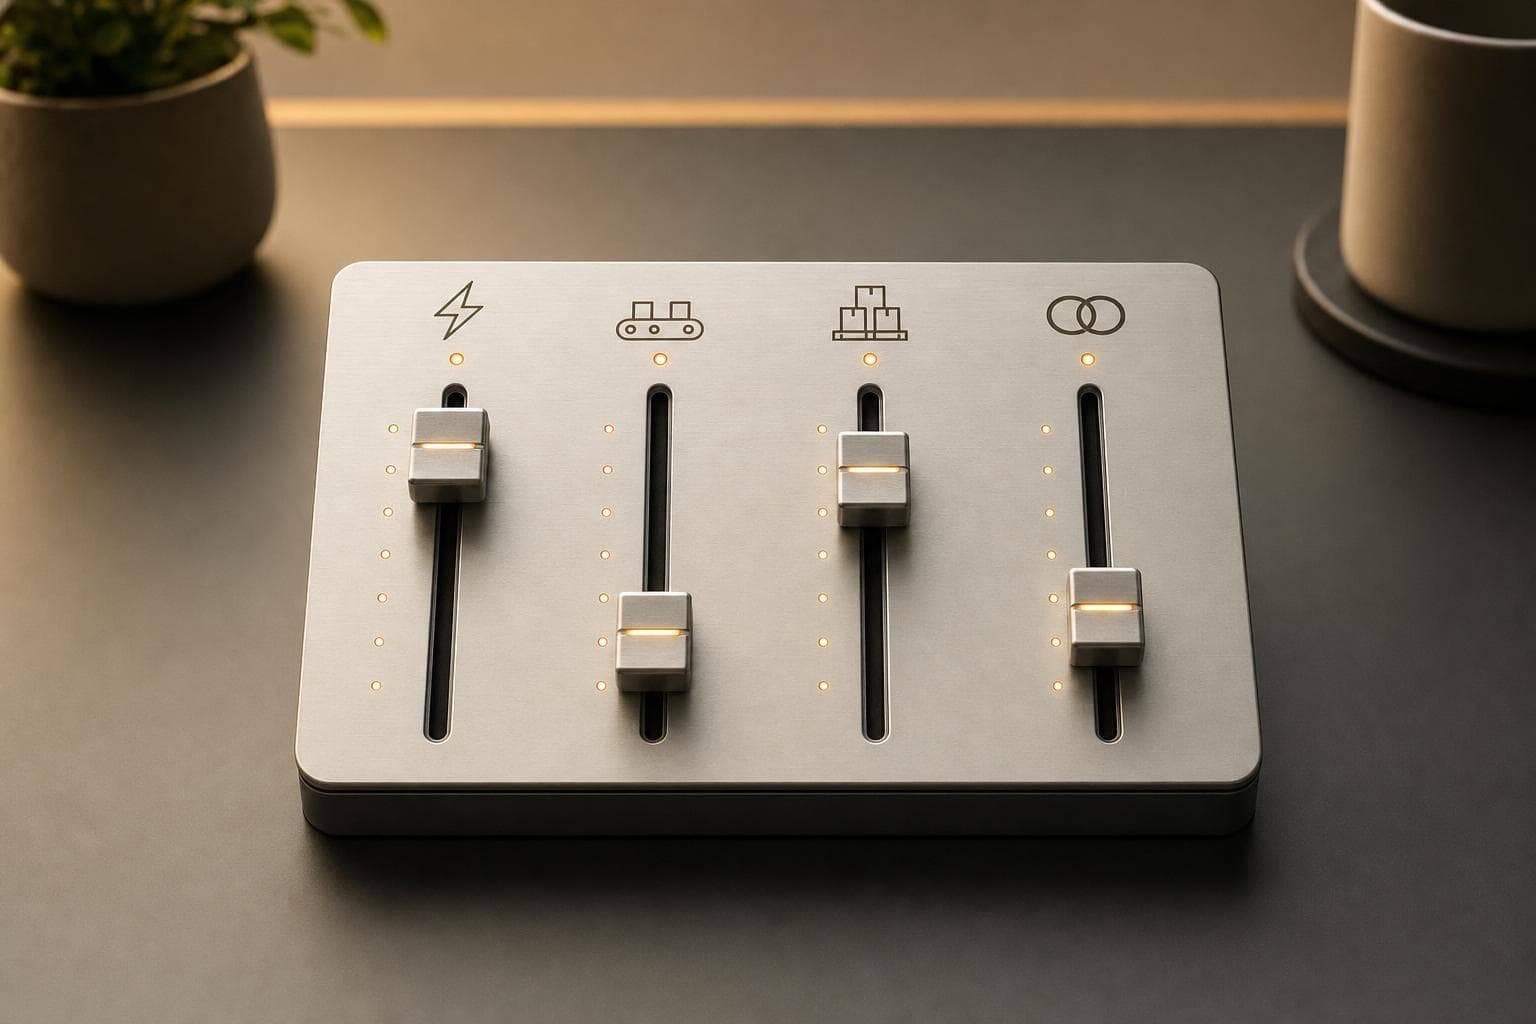
Serverless Allocation Models For ETL And AI Workloads
Match serverless settings to each workload's tightest limit: latency for inference, throughput for ETL, dbt warehouse, joins for features.
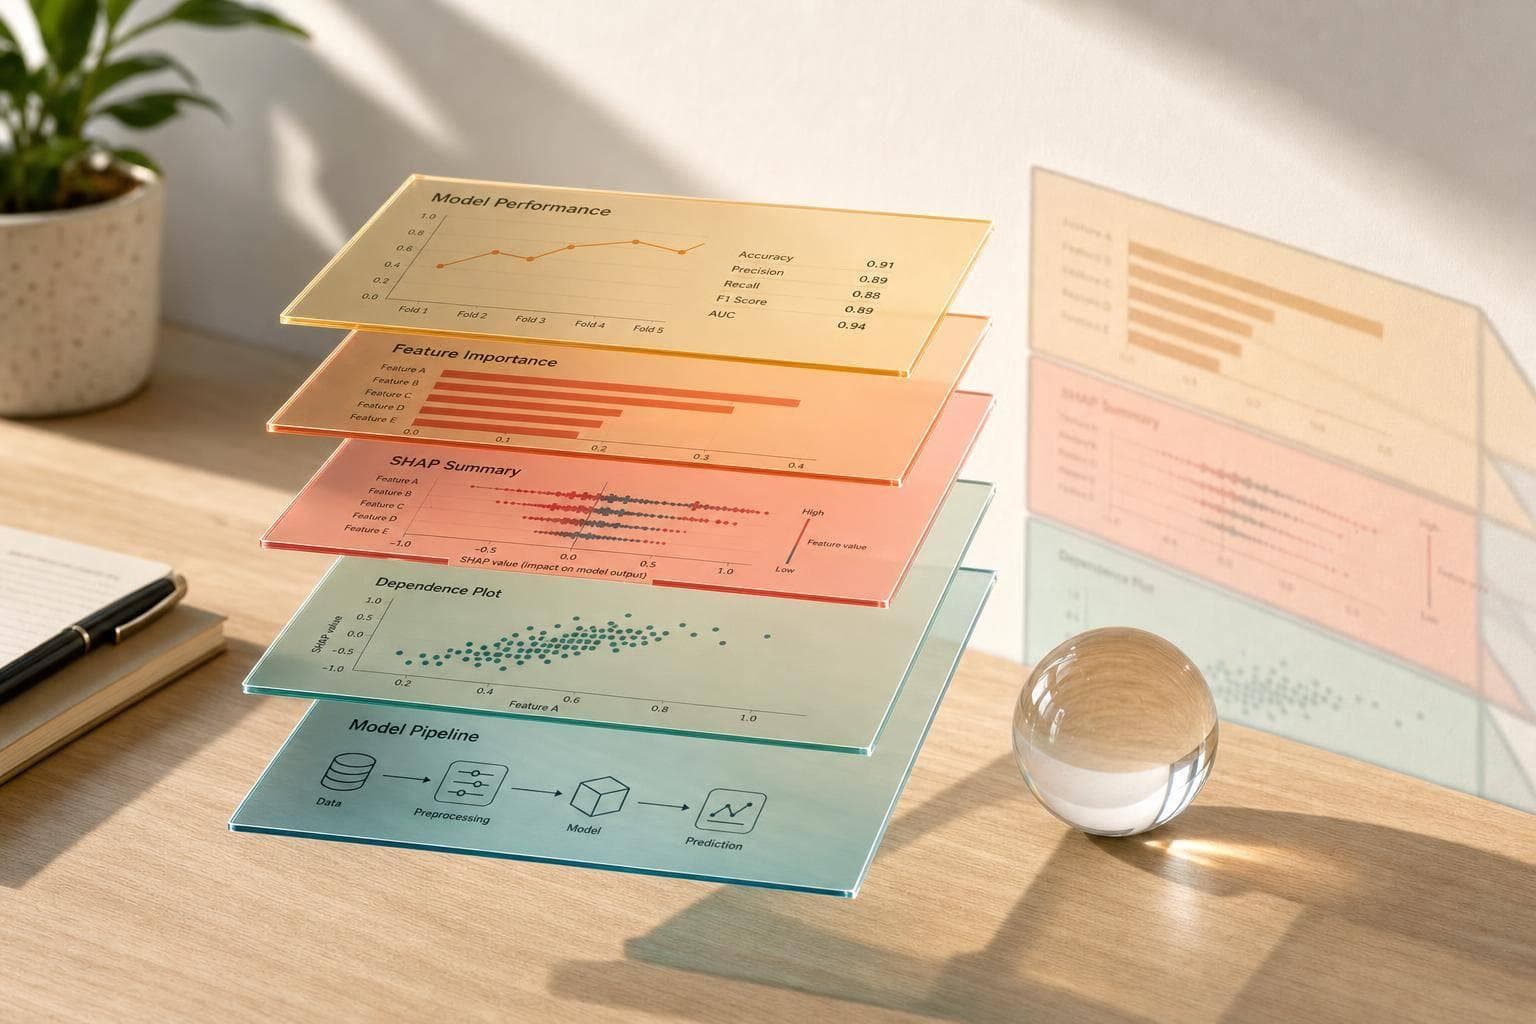
Interpreting AutoML Results with SHAP
Explain AutoML decisions with SHAP: choose the right explainer, read global/local plots, and avoid misreading feature attributions.
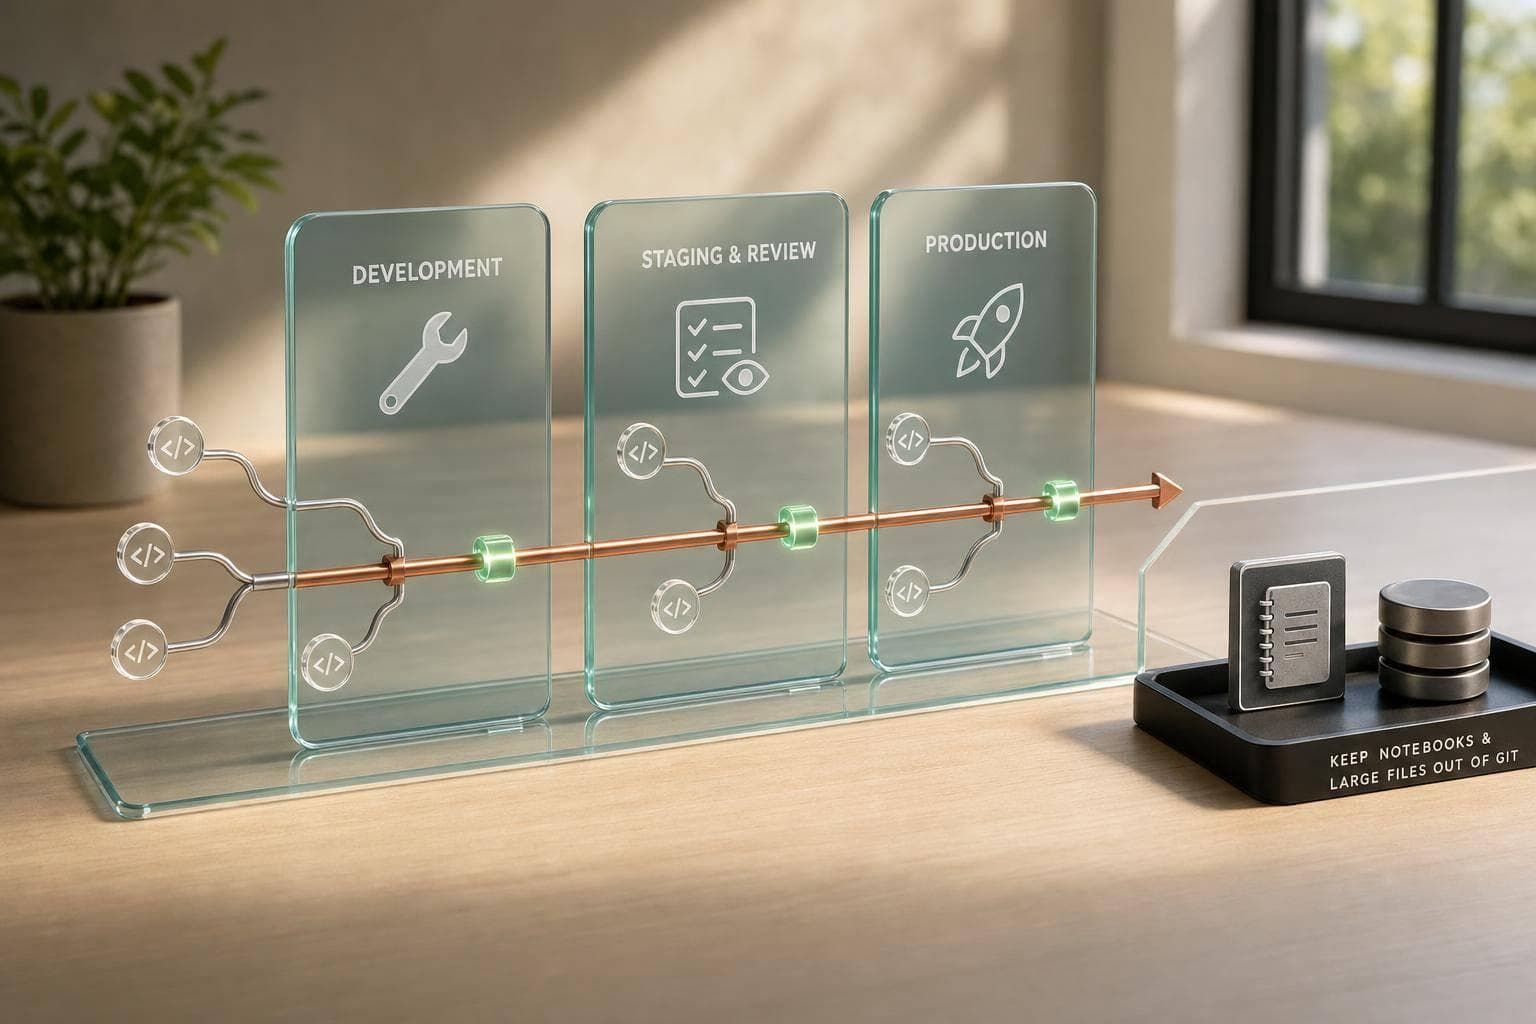
Git Workflows for Data Teams
Use one Git branch model, short-lived branches with reviews and CI, map Dev/Stage/Prod, and keep notebooks and large files out of Git.
Caching with Redis: Best Practices for Engineers
Practical Redis caching guide: design keys, set TTLs with jitter, choose eviction policies, monitor, scale, and secure production caches.
How to Optimize Data Flow in Distributed ML Pipelines
Profile pipelines, optimize storage and formats, parallelize loading and shuffling, and cache to boost GPU utilization and cut costs.