Blog
How to Build Trust in Data Pipelines with Observability
Learn how metrics, alarms, and logs help monitor data pipelines, spot failures, reduce alert noise, and debug errors to build trust in your data.
Salary Calculator
Estimate salary, bonus, equity, and net pay for data engineering roles by location, experience, and pay type.
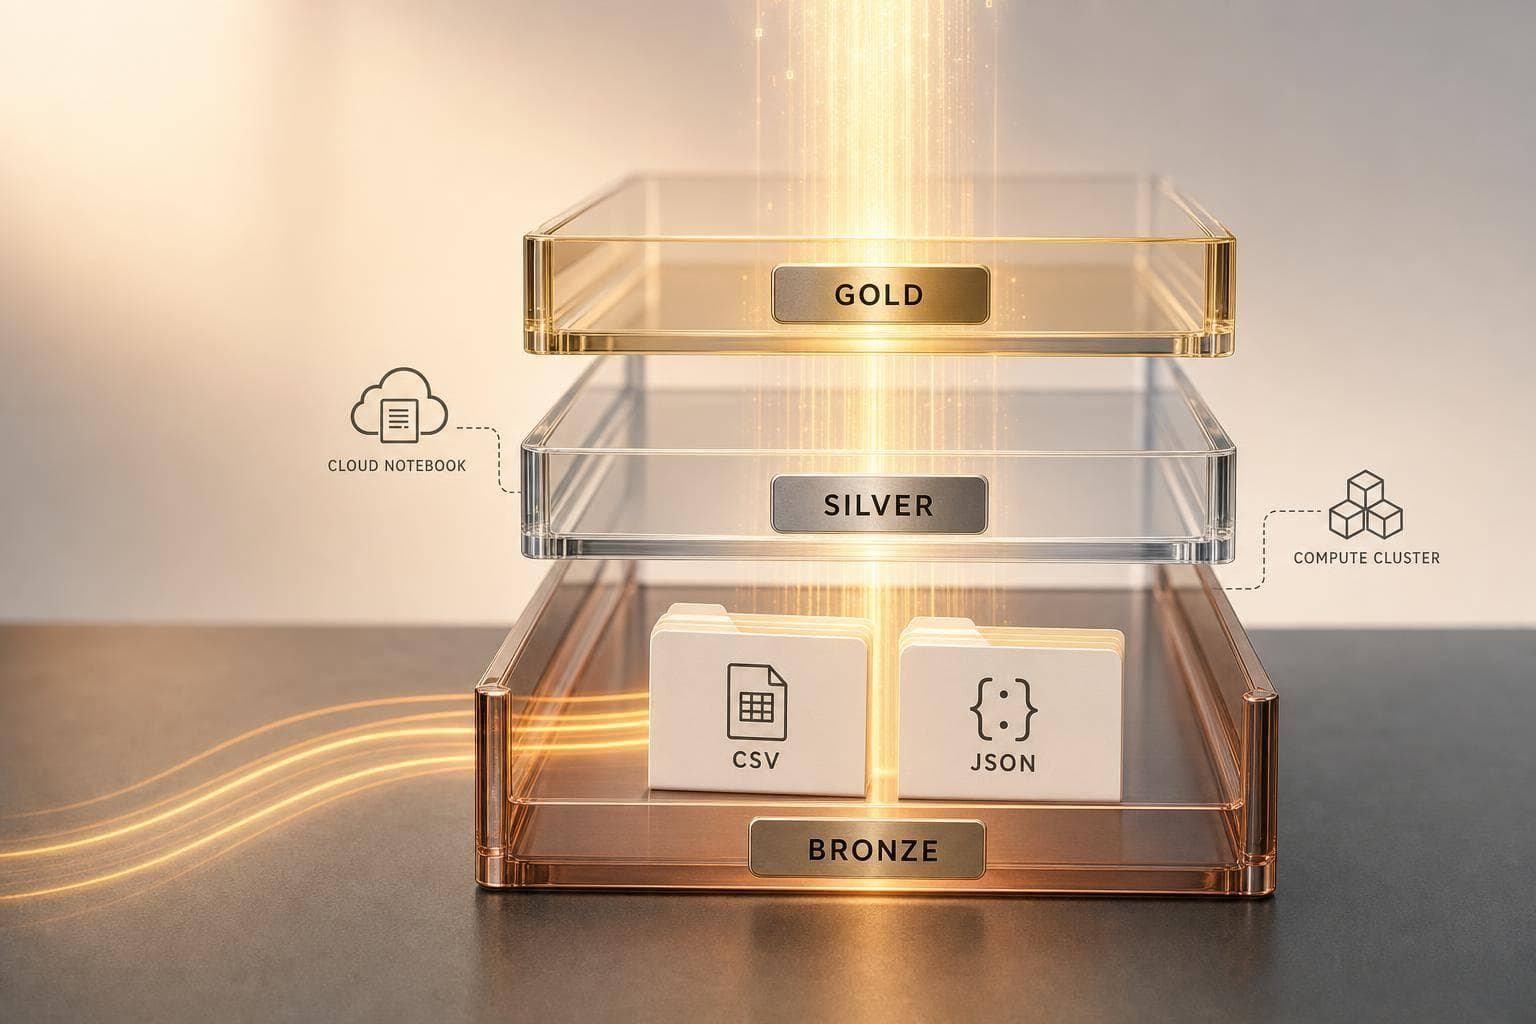
How to Build an End-to-End PySpark Data Pipeline
Learn how PySpark builds an end-to-end data pipeline with medallion architecture, Databricks, CSV, JSON, bronze, silver, and gold layers.
Data Engineer Resume Generator
Create a tailored data engineer resume draft that matches your background, target role, and job description in minutes.
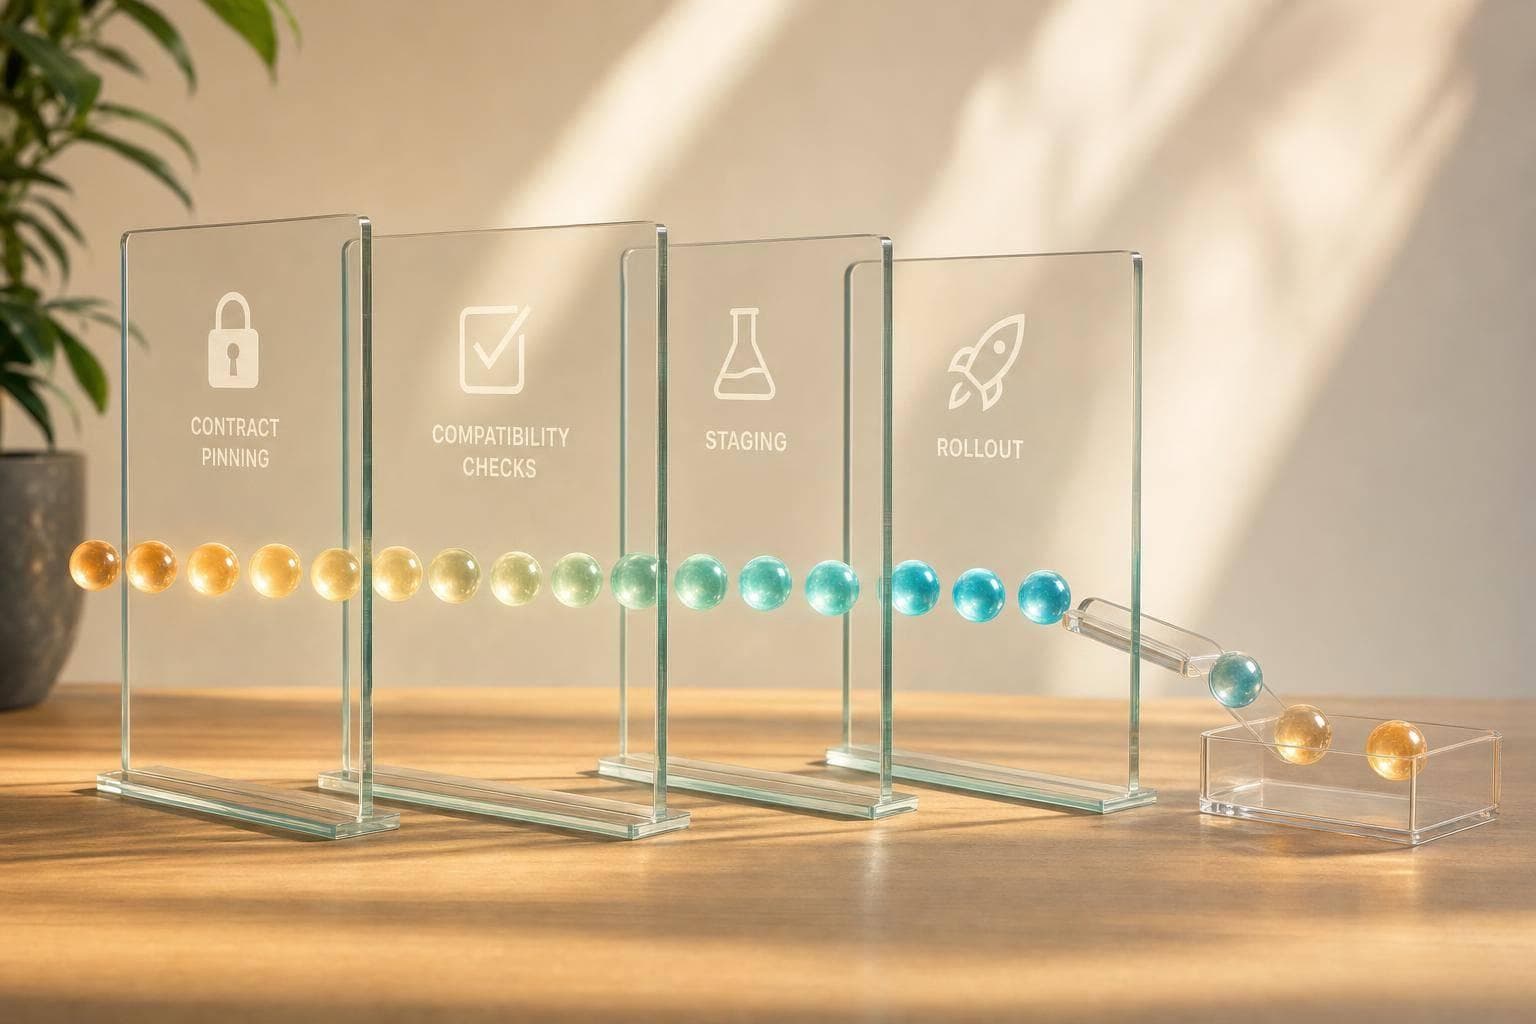
Handling Schema Drift in Event Streams
Prevent and contain schema drift in event streams: pin contracts, run compatibility and staging tests, use DLQs and staged rollouts.
Master Advanced Pytest Techniques for Reliable Testing
Learn 9 advanced Pytest tips covering fixtures, marks, parameterization, warnings, xfail, debugging, and plugins for more reliable Python tests.
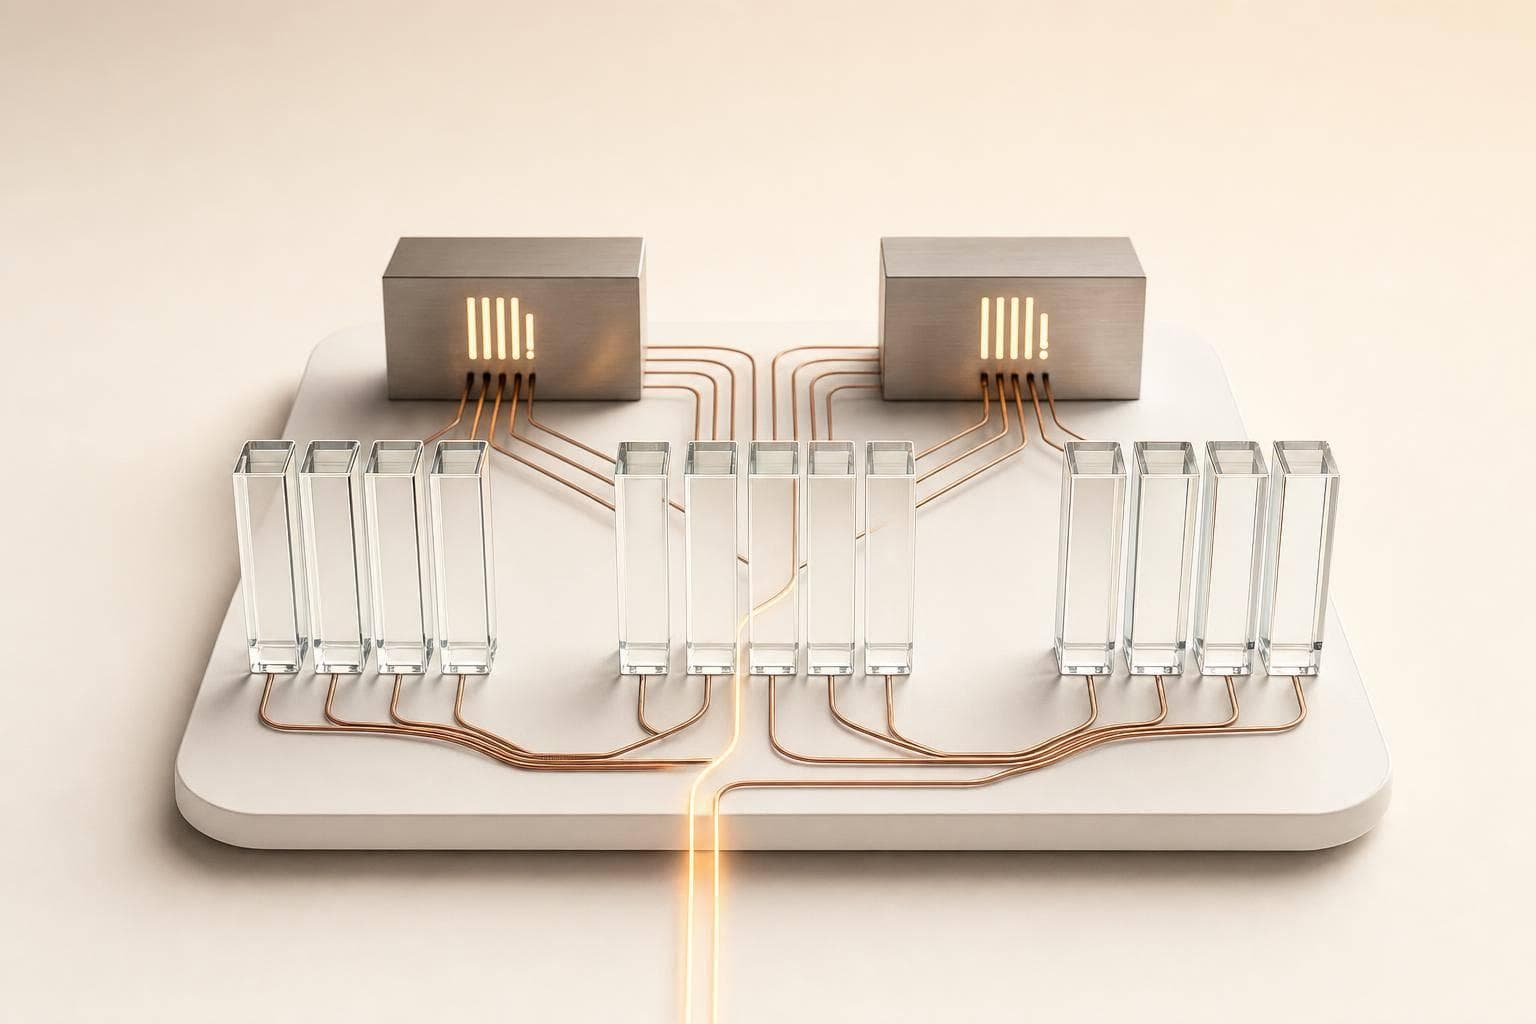
12 ClickHouse Architecture Interview Questions
Guide to ClickHouse architecture: columnar storage, MergeTree parts, partitions, shards, replicas, Distributed tables, and query flow.
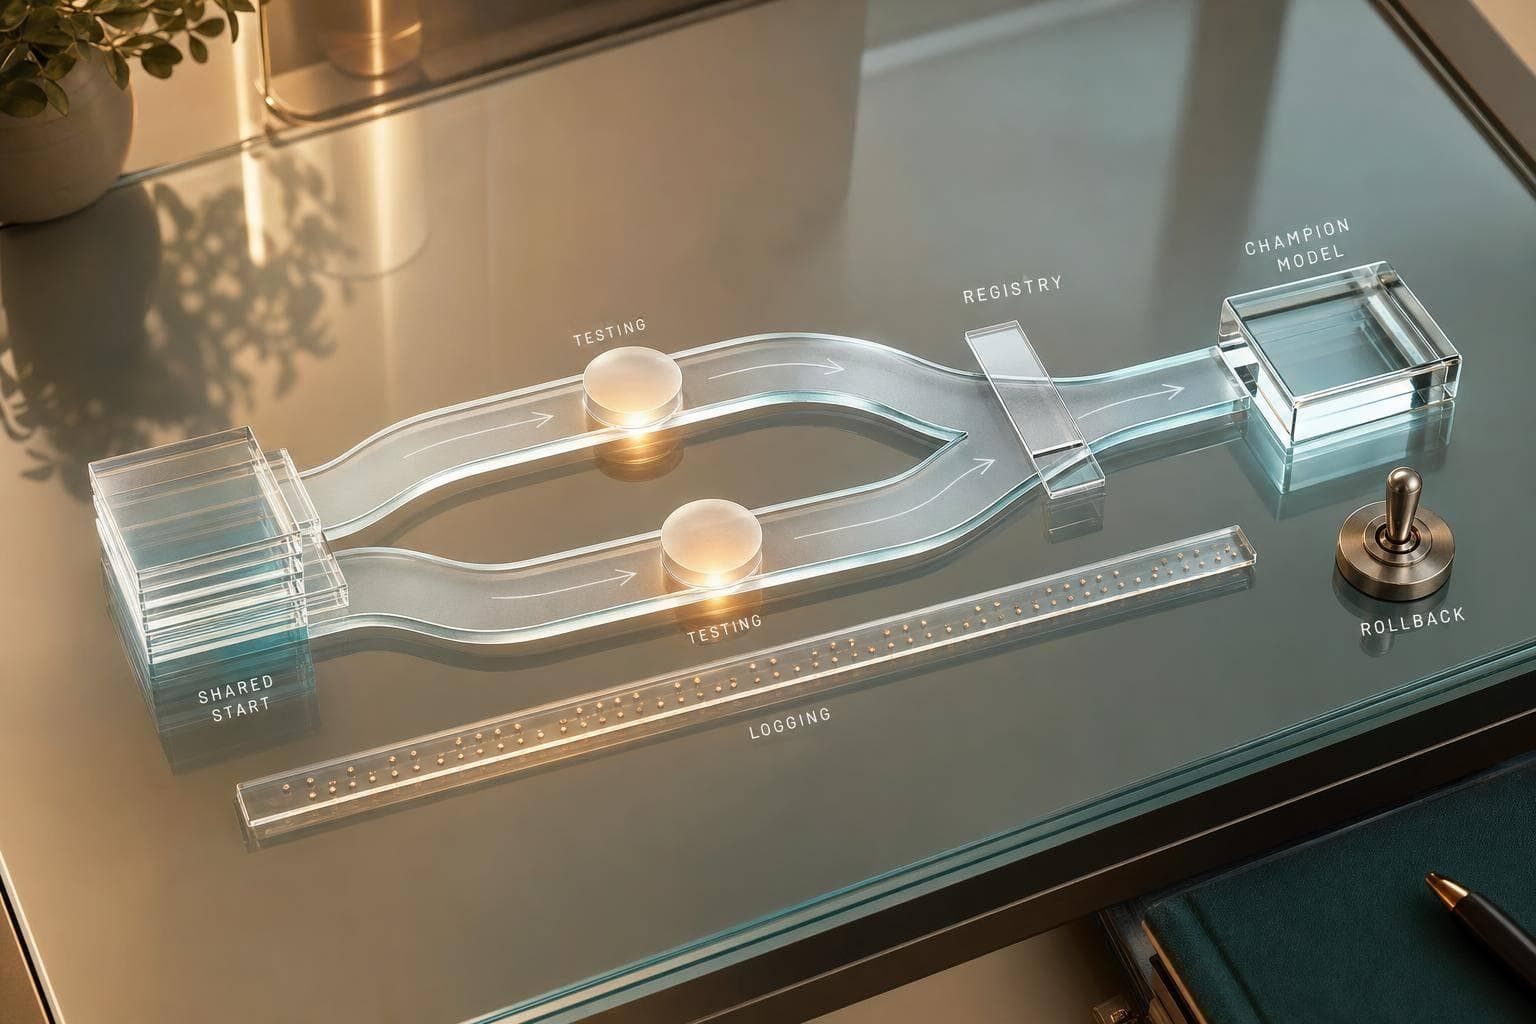
Champion-Challenger Guide for Lakehouse ML
Repeatable champion-challenger process for lakehouse ML: shared features, registry aliases, shadow/canary tests, logging, and rollback.
LIME for ML Models: 5-Step Guide
Use LIME to explain single-model predictions: build local samples, fit a weighted surrogate, and verify stability, fidelity, and scope.
How to Build AI Streams with Kafka and Flink
Low-latency AI streams: use Kafka to ingest, Flink to build features and score, with replay, lateness handling, and exactly-once delivery.
7 Signs Python Pipelines Need Performance Profiling
Seven practical signals that reveal when your Python data pipeline needs profiling to find code, orchestration, or infrastructure bottlenecks.
Serverless Allocation Models For ETL And AI Workloads
Match serverless settings to each workload's tightest limit: latency for inference, throughput for ETL, dbt warehouse, joins for features.